Category: CST 370

Students learn important data structures in computer science and acquire fundamental algorithm design techniques to get the efficient solutions to several computing problems from various disciplines. Topics include the analysis of algorithm efficiency, hash, heap, graph, tree, sorting and searching, brute force, divide-and-conquer, decrease-and-conquer, transform-and-conquer, dynamic programming, and greedy programming.

  • CST 370: Week 7

    This week we learned two new algorithm design techniques: dynamic programming and greedy algorithms. Dynamic programming is a way to avoid solving the same subproblems repeatedly by saving their answers for later use, and the greedy technique solves optimization problems by making the locally optimal choice at each step without ever going back.

    Dynamic programming

    Dynamic programming is useful when a recursive solution keeps solving the same smaller problems over and over. Instead of recomputing them, you solve each subproblem once, store the answer in a table, and build up to the final answer from the smallest cases.

    Fibonacci numbers are the classic example, where computing one value recursively ends up recomputing the earlier values many times.

    The coin-row problem is another example. You have a row of coins and want to collect the most money, but you can’t take two coins that are next to each other. At each coin you have two choices: take it and give up its neighbor, or skip it. Instead of trying every combination, you walk down the row once, and keep track of the best total you can get.

    The coin-collecting problem is the same idea on a grid, where a robot can only move right or down and wants to pick up as many coins as possible. The best total at any square is the better of the totals from the square above and the square to the left, plus any coin on that square.

    Warshall’s and Floyd’s algorithms

    Warshall’s algorithm answers the question “can I get from here to there?” for every pair of vertices in a directed graph. The book mentions spreadsheets as an example: when you change one cell, the software needs to know every other cell that depends on it, even indirectly. The algorithm starts by only allowing direct edges, then lets paths pass through the first vertex, then the first two, and so on. Each round, a new path opens up whenever you can get to the new vertex and then from it to somewhere else.

    Floyd’s algorithm uses the same structure to find the shortest distance between every pair of vertices. Each round it asks whether going through the new vertex is a shortcut compared to the best route found so far.

    The two algorithms are basically the same idea applied to different questions, and they both use dynamic programming. Instead of breaking the graph into smaller pieces, they solve a simpler version of the same problem first, with fewer vertices allowed as stops along the way. Each round builds on the answers saved from the round before, so no path ever has to be worked out from scratch.

    The greedy technique

    A greedy algorithm builds a solution one step at a time, always making the choice that looks best right now, and never going back to change it. Making change is an everyday example: to give someone 48 cents, you hand over a quarter, then dimes, then pennies. The greedy approach doesn’t always provide the optimal solution, however. If you only had quarters, dimes, and pennies and wanted to make 30 cents with the fewest coins, the greedy approach would give a quarter and five pennies, but three dimes would be optimal. Greedy algorithms are easy to come up with, but it’s hard to prove that they actually give the best answer.

    Prim’s algorithm is one where the greedy approach does work. It finds a minimum spanning tree, the cheapest set of edges that connects every vertex in a weighted graph, like the cheapest way to wire a set of buildings into one network. You start at any vertex and keep adding the cheapest edge that reaches a vertex you haven’t connected yet until everything is connected. Surprisingly, this always gives the cheapest possible tree.
  • CST 370: Week 6

    This week we learned about data structures that make common operations fast: balanced search trees and hashing for searching, and heaps for finding the largest (or smallest) value.

    Balanced search trees

    In a binary search tree, every key in a node’s left subtree is smaller than the node’s key, and every key in its right subtree is larger. Searching works like binary search: compare with the current node, then go left or right, which takes Θ(log n) time if the tree is balanced, but the shape depends on the order of insertion. If you insert keys in sorted order, every node only has a right child, the tree is basically a linked list, and search drops to Θ(n). Balanced search trees fix this by rebalancing as keys are inserted.

    AVL trees

    An AVL tree is a binary search tree where every node has a balance factor of −1, 0, or 1. The balance factor is the height of the node’s left subtree minus the height of its right subtree, with an empty tree having height −1. You have to check every node, not just the root, because a tree can look balanced at the root and still be lopsided further down.

    When an insertion makes a node’s balance factor 2 or −2, you fix the unbalanced node closest to the new leaf with one of four rotations:

    • R (right) rotation: the new key went into the left subtree of the left child
    • L (left) rotation: the mirror image, the right subtree of the right child
    • LR rotation: the new key went into the right subtree of the left child, fixed by a left rotation and then a right rotation
    • RL rotation: the mirror image of LR

    The trick is that the middle of the three keys involved always becomes the new subtree root.

    2-3 trees

    A 2-3 tree handles balancing differently. Instead of rotating, it lets nodes hold more than one key. A 2-node has one key and two children, a 3-node has two keys and three children, and all the leaves have to be on the same level. New keys always go into a leaf. If that leaf ends up with three keys, it splits: the middle key moves up into the parent, and the smallest and largest keys become their own nodes. If the parent overflows too, it splits the same way, and if the root splits, the tree gets a new root. Since the tree only ever grows at the top, all the leaves stay at the same depth, and search is Θ(log n) no matter what order the keys come in.

    Heaps

    A heap is a complete binary tree where every parent is greater than or equal to its children (for a max heap; a min heap is the reverse). Either way, the max (or min) is always at the root. Since the tree is complete, you can store it in an array without any pointers. With 1-based indexing, the children of index i are at 2i and 2i + 1, and its parent is at ⌊i/2⌋.

    To insert a key, you put it at the end and sift it up, swapping it with its parent until the parent is bigger. To remove the max, you swap the root with the last element, shrink the heap by one, and sift the new root down, swapping it with its larger child each time. Both operations take Θ(log n).

    The bottom-up heapify construction is a little tricky. Instead of inserting keys one at a time, you put them all in the array and start at the last parent, ⌊n/2⌋. Moving backward to the root, you sift each node down. By the time you reach a node, both of its subtrees are already heaps. It seems like it should be Θ(n log n), but most nodes are near the bottom and can only move down a level or two, so the whole thing is Θ(n). Heapsort builds a heap this way and then removes the max n times, putting each one into the spot that just opened up at the end of the array, sorting in place in Θ(n log n).

    Hashing

    Hashing uses a hash function, like h(k) = k mod m, to turn a key into an index in an array of size m. When two keys hash to the same index, that is called a collision. There are two main ways to handle collisions. Separate chaining (open hashing) keeps a linked list at each index. Linear probing (closed hashing) puts the key in the next open cell, wrapping around to the start if needed. The load factor α = n/m measures how full the table is. When it gets too high, collisions pile up, so you rehash everything into a bigger table. With a good hash function and a reasonable load factor, search, insert, and delete take Θ(1) on average, although the worst case is still Θ(n).

  • CST 370: Week 5

    This week covered a lot more ground than last week. We finished divide-and-conquer with quicksort and binary tree traversal and height calculations, then moved on to two new design techniques: decrease-and-conquer and transform-and-conquer.

    Divide-and-conquer

    Quicksort

    Quicksort does most of its work in the divide step. It picks a pivot and partitions the array so that everything less than or equal to the pivot is on its left and everything greater than or equal to it is on its right. The pivot is then in its final position, and the two sides are sorted recursively. No combine step is needed.

    The efficiency depends on how even the splits are. If the pivot lands in the middle each time, the recurrence has the same form as merge sort, giving Θ(n log n). In class we used the first element as the pivot, which makes the worst case an already sorted array: the pivot is always the smallest element, so one side is empty and the other has n − 1 elements, giving Θ(n²). Median-of-three partitioning avoids this for sorted input by using the median of the first, middle, and last elements as the pivot. The average case is Θ(n log n), and quicksort sorts in place, unlike merge sort.

    Binary trees

    A binary tree is either empty or a root with a left and a right subtree, which are themselves binary trees, so it fits the divide-and-conquer paradigm. The height is found by computing the heights of the left and right subtrees, taking the larger one, and adding 1 for the root. The height of the empty tree is defined as −1, so a tree with a single node has height 0. The three traversals differ only in when the root is visited:

    • Preorder: root, left, right
    • Inorder: left, root, right
    • Postorder: left, right, root

    Each of these visits every node once, so they are all Θ(n). The height calculation also visits every node once, so it is Θ(n) as well.

    Decrease-and-conquer

    Decrease-and-conquer reduces a problem to a single smaller instance of itself, solves that, and then builds on that solution to solve the original problem. Divide-and-conquer, by contrast, solves several subproblems and combines their solutions.

    Insertion sort decreases by one. Assuming the first n − 1 elements are already sorted, it inserts the last element by shifting larger elements to the right until it finds the correct spot. The worst case is a reverse-sorted array, Θ(n²). The best case is a sorted array, Θ(n), which is the opposite of quicksort with a first-element pivot. This makes it a good choice for nearly sorted input.

    Kahn’s algorithm finds a topological order of a directed acyclic graph (DAG): an ordering of the vertices in which every edge points from an earlier vertex to a later one. A common example is ordering courses by their prerequisites. The algorithm is:

    1. Compute the in-degree of every vertex
    2. Put the vertices with in-degree 0 in a queue
    3. Remove a vertex from the queue, output it, and decrement the in-degree of each vertex it has an edge to
    4. Add any neighbor whose in-degree drops to 0, and repeat

    Each step removes one vertex, leaving a smaller graph. If the queue empties before every vertex has been output, the graph has a cycle and no topological order exists. With an adjacency list, the running time is Θ(V + E).

    Transform-and-conquer

    Transform-and-conquer changes the problem into a form that is easier to solve. Presorting is the simplest example. Checking whether an array has duplicates by brute force compares every pair, Θ(n²). If we sort first with a Θ(n log n) algorithm like merge sort, any duplicates are adjacent, and one Θ(n) pass finds them. The sort dominates, so the total is Θ(n log n). The same idea works for finding the mode. This is why efficient sorting matters so much: many other problems get easier once the data is sorted.

  • CST 370: Week 4

    This week we covered merge sort as an example of the divide-and-conquer technique. Since much of the week went to reviewing for the midterm, merge sort was the only new algorithm we learned.

    Divide-and-conquer has three steps:

    1. Divide the problem into smaller subproblems of the same type
    2. Conquer (solve) each subproblem recursively
    3. Combine the subproblem solutions into a solution for the original problem

    Merge sort works by dividing an array into two halves, sorting each half recursively, and then merging the two sorted halves back together. An important point is that the two halves must be sorted before they can be merged.

    But how do we sort the two halves? By using merge sort! This is the recursive step. The base case is an array with only one element, which is already sorted by definition.

    Applying the divide-and-conquer technique to merge sort:

    1. Divide: Split the array into two approximately equal subarrays
    2. Conquer: Recursively sort each subarray using merge sort
    3. Combine: Merge the two sorted subarrays into a single sorted array

    Here is an example implementation of merge sort on Python Tutor. Notice that the comparison uses <=. This means that the element from the left half goes first when both elements are equal, which makes merge sort a stable sort, since equal elements keep their original order.

    Merge sort divides the input in half at each level of recursion, producing about log₂ n levels. At each level, merging the two halves takes linear time, giving merge sort a time complexity of Θ(n log(n)).

  • CST 370: Week 3

    Week 3 covered a few brute force algorithms: sequential search, string matching, and the two graph traversal algorithms (DFS and BFS). We also started learning about divide-and-conquer algorithms, which we will study more in the coming weeks.

    Searching and string matching

    Sequential search is a common brute force technique. Basically, you just check every item until you find the one you’re looking for.

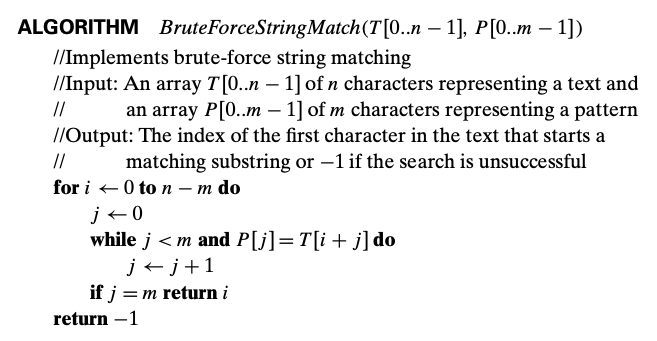
    To find a substring in a string, we can use brute-force string matching. The main idea is that you check a pattern of m characters at each of the n − m + 1 possible positions, shifting one position to the right on a mismatch, until you find the complete substring or reach the the end of the window (in which case there is no match). Levitin’s textbook provides the following pseudocode:

    The worst case is m(n − m + 1), or O(nm), because the inner loop runs m times for each of the n - m + 1 iterations of the outer loop.

    Exhaustive search

    Exhaustive search is brute force applied to combinatorial problems, like the traveling salesman problem (TSP). The main idea is that you generate every possible combination and then pick the best one. For TSP, this means generating every possible tour that visits each city exactly once and returns to the starting city, in order to calculate the total cost of each tour and choose the shortest one. Exhaustive search is guaranteed to find the optimal solution, but it becomes impractical for large inputs because the number of possible solutions grows extremely quickly.

    DFS and BFS

    Depth-first search (DFS) and breadth-first search (BFS) are two common graph traversal algorithms. DFS explores as far as possible along one path before backtracking and often uses recursion. BFS explores the graph level by level, visiting all neighboring vertices before moving farther away and is usually implemented with a queue. Both can be used to visit all reachable vertices, but they explore the graph in different orders.

  • CST 370: Week 2

    This week we dove more deeply into the analysis of algorithms. Last week introduced order of growth, and this week expanded on that with asymptotic notation, analysis of non-recursive and recursive algorithms, and the first design technique, brute force.

    Asymptotic notation

    NotationMeaningFormal condition
    O(g(n))Upper boundt(n) ≤ c·g(n) for all n ≥ n₀
    Ω(g(n))Lower boundt(n) ≥ c·g(n) for all n ≥ n₀
    Θ(g(n))Tight boundc₁·g(n) ≤ t(n) ≤ c₂·g(n) for all n ≥ n₀

    The table above is based on the definitions given in section 2.2 of the Levitin’s textbook. Big-O, Big-Omega, and Big-Theta each compare an algorithm’s running time t(n) to a simpler function g(n), such as n or n².

    For orders of growth, we only care about large inputs, so each condition has to hold from some starting size n₀ onward.

    O(g(n)) is the upper bound: after n₀, t(n) never grows faster than some constant multiple c of g(n).

    Ω(g(n)) is the lower bound: after n₀, t(n) always grows at least as fast as a constant multiple of g(n).

    Θ(g(n)) is the tight bound: t(n) stays between two constant multiples of g(n), so it is both O(g(n)) and Ω(g(n)) and has the same order of growth.

    The constants are what let us ignore details. You can pick any c and n₀ that make the inequality true, so coefficients and lower-order terms don’t change the classification. For example, 2n + 3 is Θ(n) because n ≤ 2n + 3 ≤ 3n for all n ≥ 3.

    Analyzing non-recursive algorithms

    To analyze a non-recursive algorithm, you count the basic operation, which is usually found in the innermost loop. Once the basic operation is identified, you determine how many times it runs, in terms of n, and simplify to get the order of growth.

    For example, if an algorithm’s basic operation is in a nested loop, that runs n times for the outer loop and n times for the inner loop, then the order of growth is Θ(n²)

    Analyzing recursive algorithms

    A recursive algorithm’s count is written as a recurrence relation plus an initial condition from the base case, which can then be solved by backward substitution.

    To solve a recurrence relation, substitute repeatedly until a pattern appears, generalize the pattern in terms of i, and then choose the i that reaches the base case, in order to express the relation in terms of n.

    Brute force

    Brute force means solving a problem directly from its definition, usually by trying every possibility. It can often be slow, but it’s a good starting point towards a more efficient solution.

  • CST 370: Week 1

    Week 1 kicked off the course with a series of lectures on some fundamental concepts in algorithm design and analysis, which should provide a foundation for the rest of the course. Topics covered include what an algorithm actually is, how to analyze an algorithm, pseudocode conventions, and common data structures we’ll be using, like graphs and trees.

    What an algorithm is

    While there is no universally-agreed definition for what an algorithm actually is, the textbook provides the following:

    An algorithm is a sequence of unambiguous instructions for solving a problem, i.e., for obtaining a required output for any legitimate input in a finite amount of time.

    From this definition, we can extract five properties of an algorithm:

    1. It solves a problem
    2. It takes a well-defined input
    3. It produces a well-defined output
    4. It requires a finite amount of time to run
    5. It is comprised of a sequence of clear instructions

    One thing to keep in mind is that there is a difference between an algorithm and a procedure. A procedure may contain vague instructions, but an algorithm leaves nothing ambiguous; every step in an algorithm must be clearly defined.

    Introduction to Algorithm Analysis

    Algorithm analysis considers both time and space, but for this course, we will focus on time complexity. We care mostly about the order of growth. The handout presents eight common time efficiency classes.

    NameSample FunctionExample
    Constant time1Looking up an item in a hash table
    Logarithmic timelog nBinary search in a sorted array with n numbers
    Linear timenSumming n numbers in an array
    Linearithmic timen * log nMerge sort
    Quadratic timen²Bubble sort
    Cubic timen³Multiplication of two n x n matrices
    Exponential time2ⁿTower of Hanoi problem with n disks
    Factorial timen!TSP (Traveling Salesman Problem) using a brute-force approach

    Homework

    Finding the shortest distance between two numbers

    This homework problem involved reading a list of distinct integers and finding the smallest distance between any two of them.

    The brute-force approach would compare all pairs against each other, which would take quadratic time. The trick to solving this problem efficiently is to sort the numbers first, so that once the numbers are in order, the closest pairs are adjacent.

    Java’s Arrays.sort contributes n log n to the running time, making it the algorithm’s basic operation. Once the array of integers is sorted, the closest pair can be found in linear time.

    Finding the intersection of a set of ranges

    This homework problem involved reading a set of integer ranges and finding their intersection. To solve this problem, you need to find the maximum lower bound and the minimum upper bound of the input sets. If the maximum lower bound is less than or equal to the minimum upper bound, then there is a valid intersection, otherwise there is no valid intersection. This only takes a single pass, running in linear time.